

Artificial Intelligence has evolved from rule-based systems that followed predefined instructions into sophisticated technologies capable of learning from enormous volumes of data, recognizing patterns, generating content, making predictions and assisting with complex decisions.
At the center of much of this transformation is Deep Learning.
Deep learning has powered major advances in computer vision, speech recognition, natural language processing, autonomous systems and scientific discovery. More recently, it has become one of the technological foundations behind Generative AI, Large Language Models (LLMs), multimodal AI and foundation models.
From recognizing objects in an image to translating languages, generating text, creating images, analyzing medical scans and enabling intelligent assistants, deep learning has become a fundamental component of modern Artificial Intelligence.
But what exactly is deep learning? How does it work? How is it different from traditional machine learning? And where is the technology heading?
This guide explores the evolution, architecture, applications, challenges and future of deep learning.
What Is Deep Learning?
Deep learning is a branch of machine learning that uses multi-layered artificial neural networks to learn patterns and representations from data. This learning methodology can be supervised, semi-supervised or unsupervised.
Deep learning architectures such as neural networks and convolutional neural networks have been applied to fields including computer vision, speech recognition, natural language processing, audio recognition, social network filtering, machine translation where they have produced results comparable to and in some cases superior to human experts.
Brief History
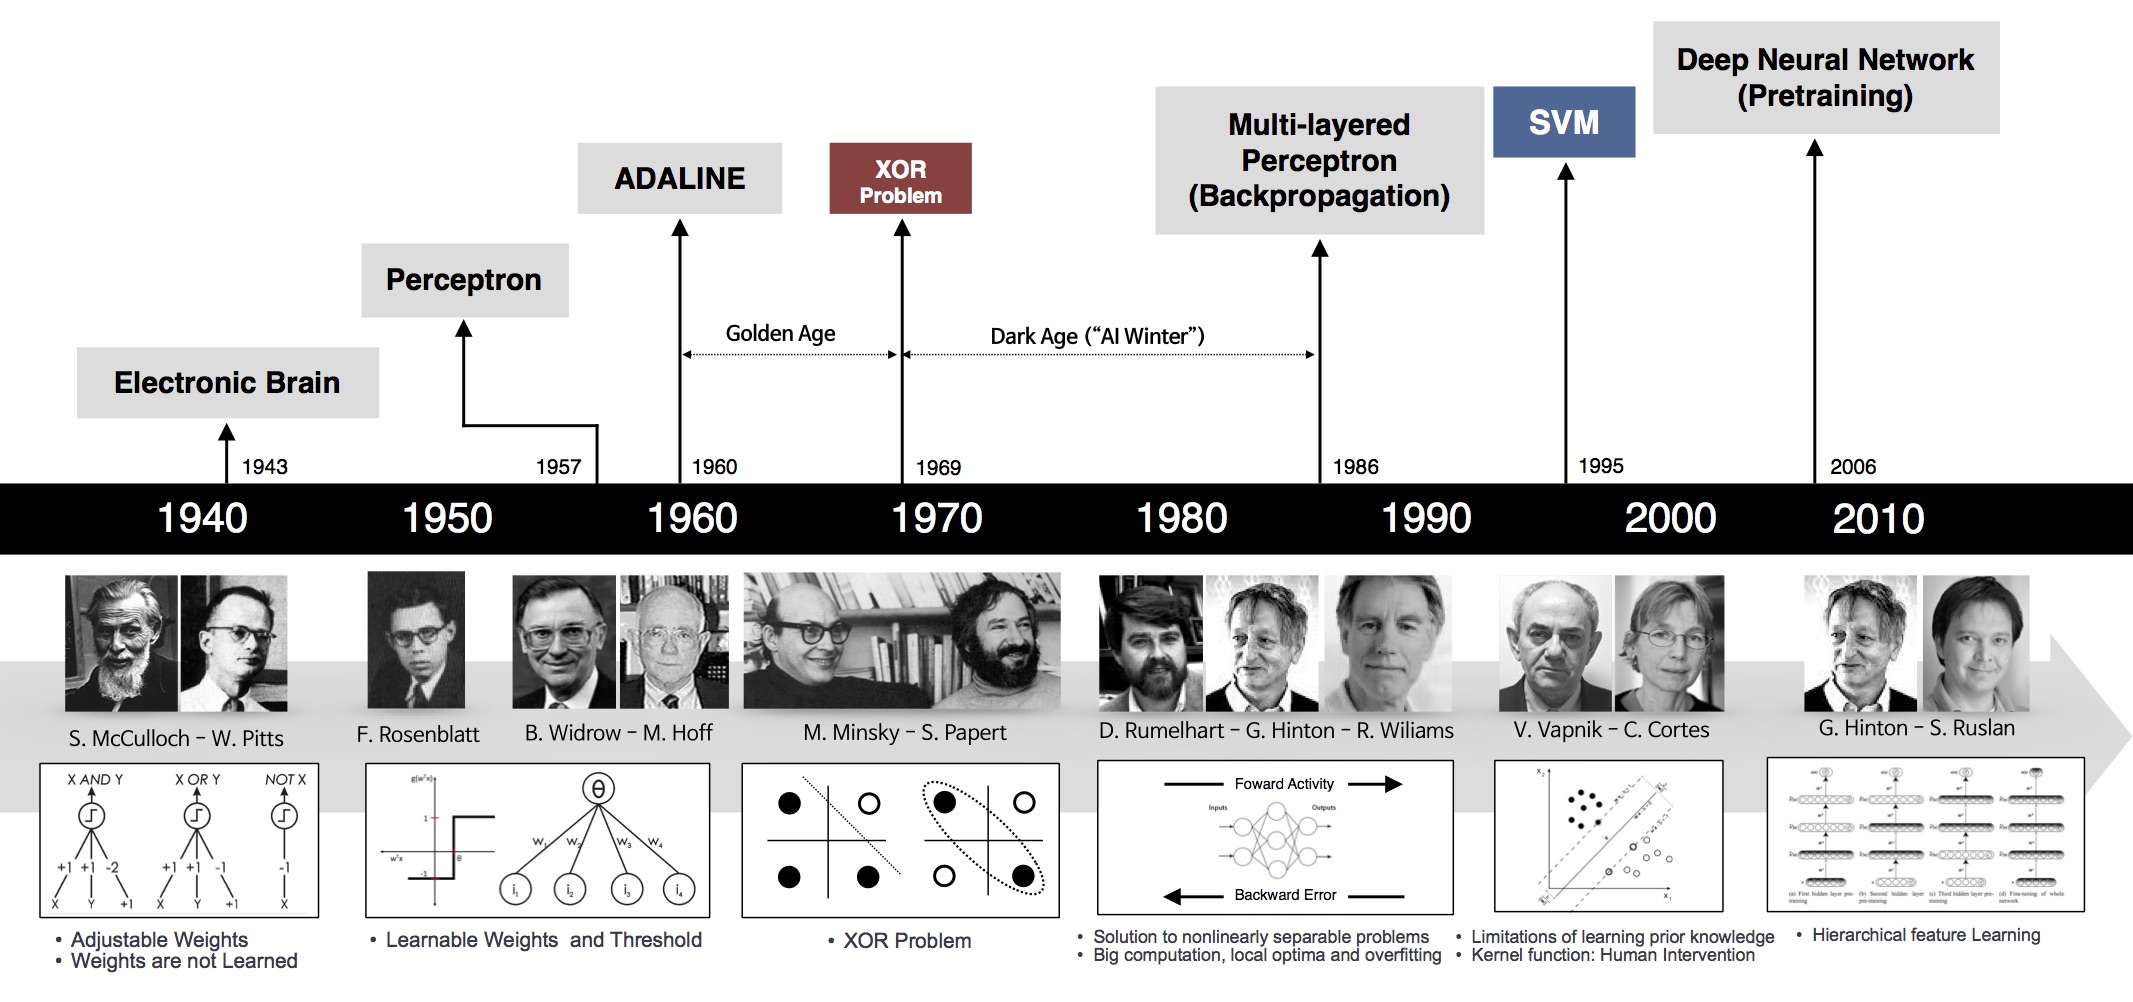
1943: The history of Deep Learning can be traced back to 1943, when Walter Pitts and Warren McCulloch created a computer model based on the neural networks of the human brain. They used a combination of algorithms and mathematics they called “threshold logic” to mimic the thought process. Since that time, Deep Learning has evolved steadily, with only two significant breaks in its development. Both were tied to the infamous Artificial Intelligence winters.
 1960: Henry J. Kelley is given credit for developing the basics of a continuous Back Propagation Model in 1960. In 1962, a simpler version based only on the chain rule was developed by Stuart Dreyfus. While the concept of back propagation (the backward propagation of errors for purposes of training) did exist in the early 1960s, it was clumsy and inefficient, and would not become useful until 1985.
The earliest efforts in developing Deep Learning algorithms came from Alexey Grigoryevich Ivakhnenko (developed the Group Method of Data Handling) and Valentin Grigorʹevich Lapa (author of Cybernetics and Forecasting Techniques) in 1965. They used models with polynomial (complicated equations) activation functions, that were then analyzed statistically. From each layer, the best statistically chosen features were then forwarded on to the next layer (a slow, manual process).
1970: During the 1970’s the first AI winter kicked in, the result of promises that couldn’t be kept. The impact of this lack of funding limited both DL and AI research. Fortunately, there were individuals who carried on the research without funding.
The first “convolutional neural networks” were used by Kunihiko Fukushima. Fukushima designed neural networks with multiple pooling and convolutional layers. In 1979, he developed an artificial neural network, called Neocognitron, which used a hierarchical, multilayered design. Allowed the computer the “learn” to recognize visual patterns. The networks resembled modern versions, but were trained with a reinforcement strategy of recurring activation in multiple layers, which gained strength over time. Additionally, Fukushima’s design allowed important features to be adjusted manually by increasing the “weight” of certain connections.
Many of the concepts of Neocognitron continue to be used. The use of top-down connections and new learning methods have allowed for a variety of neural networks to be realized. When more than one pattern is presented at the same time, the Selective Attention Model can separate and recognize individual patterns by shifting its attention from one to the other. (The same process many of us use when multitasking). A modern Neocognitron can not only identify patterns with missing information (for example, an incomplete number 5), but can also complete the image by adding the missing information. This could be described as “inference.”
Back propagation, the use of errors in training Deep Learning models, evolved significantly in 1970. This was when Seppo Linnainmaa wrote his master’s thesis, including a FORTRAN code for back propagation. Unfortunately, the concept was not applied to neural networks until 1985. This was when Rumelhart, Williams, and Hinton demonstrated back propagation in a neural network could provide “interesting” distribution representations. Philosophically, this discovery brought to light the question within cognitive psychology of whether human understanding relies on symbolic logic (computationalism) or distributed representations (connectionism). In 1989, Yann LeCun provided the first practical demonstration of backpropagation at Bell Labs. He combined convolutional neural networks with back propagation onto read “handwritten” digits. This system was eventually used to read the numbers of handwritten checks.
1980-90: This time is also when the second AI winter (1985-90s) kicked in, which also effected research for neural networks and Deep Learning. Various overly-optimistic individuals had exaggerated the “immediate” potential of Artificial Intelligence, breaking expectations and angering investors. The anger was so intense, the phrase Artificial Intelligence reached pseudoscience status. Fortunately, some people continued to work on AI and DL, and some significant advances were made. In 1995, Dana Cortes and Vladimir Vapnik developed the support vector machine (a system for mapping and recognizing similar data). LSTM (long short-term memory) for recurrent neural networks was developed in 1997, by Sepp Hochreiter and Juergen Schmidhuber.
During the late 1990s and 2000s, increasingly powerful and programmable graphics processing units (GPUs) provided computational capabilities that would eventually accelerate neural-network training dramatically.
 2000: Around the year 2000, The Vanishing Gradient Problem appeared. It was discovered “features” (lessons) formed in lower layers were not being learned by the upper layers, because no learning signal reached these layers. This was not a fundamental problem for all neural networks, just the ones with gradient-based learning methods. The source of the problem turned out to be certain activation functions. A number of activation functions condensed their input, in turn reducing the output range in a somewhat chaotic fashion. This produced large areas of input mapped over an extremely small range. In these areas of input, a large change will be reduced to a small change in the output, resulting in a vanishing gradient. Two solutions used to solve this problem were layer-by-layer pre-training and the development of long short-term memory.
In 2001, a research report by META Group (now called Gartner) described the challenges and opportunities of data growth as three-dimensional. The report described the increasing volume of data and the increasing speed of data as increasing the range of data sources and types. This was a call to prepare for the onslaught of Big Data, which was just starting.
In 2009, Fei-Fei Li, an AI professor at Stanford launched ImageNet, assembled a free database of more than 14 million labeled images. The Internet is, and was, full of unlabeled images. Labeled images were needed to “train” neural nets. Professor Li said, “Our vision was that Big Data would change the way machine learning works. Data drives learning.”
A landmark breakthrough arrived in 2012 with AlexNet, a deep convolutional neural network that achieved dramatically improved performance in the ImageNet Large Scale Visual Recognition Challenge. Its success demonstrated the potential of combining deep neural networks, large datasets and GPU computing. AlexNet also successfully employed techniques including rectified linear units (ReLUs) and dropout.
Also in 2012, Google Brain released the results of an unusual project known as The Cat Experiment. The free-spirited project explored the difficulties of “unsupervised learning.” Deep Learning Deep learning can use supervised, semi-supervised, self-supervised or unsupervised learning approaches. Unlike supervised learning, which typically relies on labeled examples, unsupervised learning seeks to identify patterns and representations within unlabeled data.
The Cat Experiment used a neural net spread over 1,000 computers. Ten million “unlabeled” images were taken randomly from YouTube, shown to the system, and then the training software was allowed to run. At the end of the training, one neuron in the highest layer was found to respond strongly to the images of cats. Andrew Ng, the project’s founder said, “We also found a neuron that responded very strongly to human faces.” Unsupervised learning remains a significant goal in the field of Deep Learning.
The Cat Experiment works about 70% better than its forerunners in processing unlabeled images. However, it recognized less than a 16% of the objects used for training, and did even worse with objects that were rotated or moved.
2014 — Generative Adversarial Networks (GANs)
In 2014, Ian Goodfellow and collaborators introduced Generative Adversarial Networks (GANs), in which two neural networks—a generator and a discriminator—compete during training. GANs became highly influential in generating realistic images, synthetic data and other forms of digital content.
2017 — Transformers
In 2017, researchers introduced the Transformer architecture, using attention mechanisms to model relationships within data without relying primarily on recurrent processing. Transformers dramatically improved scalability and became the architectural foundation for modern Large Language Models and many Generative AI systems.
2018–2020 — Large-Scale Pretrained Language Models
Between 2018 and 2020, models such as BERT and GPT demonstrated the power of pretraining large neural networks on vast amounts of text and subsequently adapting them to different tasks. This shifted Natural Language Processing toward increasingly capable general-purpose pretrained models.
2020-2022 — Foundation Models and Generative AI
During the early 2020s, increasingly large pretrained models evolved into what became known as foundation models—models trained broadly and adaptable to many downstream applications. Their rapid development accelerated Generative AI across text, images, code, audio and other forms of digital content.
2022 Onward — Multimodal and Agentic AI Systems
From 2022 onward, AI increasingly moved beyond text-only systems toward multimodal models capable of working across text, images, audio and video. At the same time, agentic AI systems began combining advanced models with tools, memory, planning and execution capabilities, moving AI from primarily generating responses toward completing increasingly complex tasks and workflows.
How Does Deep Learning Work?
Deep learning uses artificial neural networks consisting of interconnected computational units commonly called neurons.
A simplified neural network contains three basic components:
1. Input Layer
The input layer receives data.
Depending on the application, this might include:
- Image pixels
- Words or tokens
- Audio signals
- Sensor readings
- Financial data
- Scientific measurements
2. Hidden Layers
Hidden layers transform the information.
Each layer learns representations that may become progressively more abstract.
A computer-vision model, for example, might learn:
Pixels → Edges → Shapes → Features → Objects
A language model may learn increasingly sophisticated relationships between tokens, phrases, syntax, semantics and broader context.
3. Output Layer
The output layer produces the prediction or result.
Depending on the system, the output might represent:
- An object classification
- A predicted value
- A translated sentence
- Generated text
- A detected anomaly
- A probability
- A recommended action
How Does a Neural Network Learn?
Training involves repeatedly exposing a neural network to data and adjusting its internal parameters.
A simplified training cycle looks like this:
Input Data → Prediction → Compare With Desired Outcome → Calculate Error → Adjust Parameters → Repeat
The objective is to reduce the model’s error over repeated training cycles.
One of the most important mechanisms used to accomplish this is backpropagation.
Backpropagation calculates how much different parameters contributed to an error and allows an optimization algorithm to adjust those parameters.
When this process occurs across enormous datasets and networks containing millions or billions of parameters, models can learn extremely complex representations.
Major Deep Learning Architectures
Deep learning is not one single architecture.
Different neural-network designs are suited to different types of problems.
Convolutional Neural Networks (CNNs)
Convolutional Neural Networks became one of the most influential architectures in computer vision.
CNNs are particularly effective at identifying spatial patterns in images.
They have been widely applied to:
- Image classification
- Object recognition
- Medical imaging
- Facial recognition
- Manufacturing inspection
- Satellite imagery
- Autonomous vehicles
CNNs learn increasingly complex visual features across multiple layers.
Recurrent Neural Networks (RNNs)
Recurrent Neural Networks were designed for sequential information.
Unlike conventional feed-forward networks, RNNs incorporate information from previous steps in a sequence.
They have historically been used for:
- Language processing
- Speech recognition
- Time-series analysis
- Sequence prediction
However, conventional RNNs can struggle with long-range dependencies.
Architectures such as LSTM and GRU networks were developed to address some of these limitations.
Transformers and Attention
Transformers represented a major evolution in deep learning.
Rather than processing information primarily through recurrence, transformers rely heavily on a mechanism called attention.
Attention allows a model to determine which parts of the input are most relevant to other parts.
Consider the sentence:
The company launched the product because it saw strong demand.
Understanding what “it” refers to requires recognizing relationships between different words.
Attention mechanisms help neural networks model relationships like these across sequences.
Why Transformers Matter
Transformers are particularly powerful because they can:
- Capture long-range relationships
- Process information efficiently in parallel
- Scale to enormous datasets
- Learn sophisticated contextual representations
- Support many different modalities
Transformers have become central to:
- Large Language Models
- Generative AI
- Machine Translation
- Computer Vision
- Multimodal AI
- Scientific AI
- Speech and Audio Processing
Their influence now extends far beyond language.
What Are Foundation Models?
One of the most important developments in modern deep learning is the emergence of foundation models.
A foundation model is trained on broad datasets and can subsequently be adapted to perform many different downstream tasks.
Instead of creating an entirely new model for every application, organizations can start with a pretrained model and customize or connect it to specific applications.
Foundation models can support capabilities such as:
- Question answering
- Content generation
- Summarization
- Translation
- Coding
- Image generation
- Classification
- Information extraction
- Scientific analysis
- Decision support
This approach has significantly changed how AI systems are developed.
Large Language Models
Large Language Models (LLMs) are deep-learning models designed to learn statistical patterns and relationships in language and other tokenized information.
Modern LLMs are generally based on transformer architectures.
During pretraining, models learn from very large datasets by predicting or reconstructing information.
Through this process, they develop representations useful for tasks such as:
- Writing
- Question answering
- Summarization
- Translation
- Reasoning
- Coding
- Information extraction
- Conversational interaction
LLMs are one of the most visible applications of deep learning, but they represent only part of the broader field.
Generative AI and Deep Learning
Traditional AI systems frequently focus on classification or prediction.
Generative AI goes further by creating new outputs.
Deep-learning systems can now generate:
- Text
- Images
- Music
- Speech
- Video
- Software code
- 3D content
- Synthetic data
Two important technological families behind generative AI are transformer models and diffusion models.
Diffusion Models
Diffusion models have become particularly important for generative media.
During training, these models learn how to reconstruct data after noise has progressively been introduced.
When generating content, the process can effectively operate in reverse—starting from noise and progressively creating a structured output.
Diffusion techniques have been widely used in image generation and are increasingly relevant to video, audio and other modalities.
Multimodal Deep Learning
Human intelligence does not operate through text alone.
We simultaneously interpret images, language, sound, movement and physical context.
Modern AI systems are increasingly moving in the same direction.
Multimodal AI combines information from multiple data types.
A multimodal model might be able to:
- Examine an image
- Understand a spoken question
- Read accompanying text
- Analyze a chart
- Generate an explanation
This convergence is creating increasingly versatile AI systems.
Training and Adapting Deep Learning Models
There are several major approaches to developing deep-learning systems.
Training From Scratch
A model can be designed and trained using a new dataset.
This provides substantial control but may require enormous amounts of:
Data + Compute + Time + Expertise + Capital
Consequently, training very large models from scratch is practical primarily for organizations with substantial resources.
Transfer Learning
Transfer learning allows knowledge learned from one problem to be applied to another.
Instead of beginning from zero, developers start with a pretrained model and adapt it to a new task.
This can dramatically reduce training requirements.
Fine-Tuning
Fine-tuning further trains a pretrained model using task-specific or domain-specific data.
For example, a general model could be adapted for:
- Legal documents
- Financial analysis
- Healthcare terminology
- Customer support
- Engineering applications
Fine-tuning has become an important method of adapting foundation models.
Retrieval-Augmented Generation
Not every piece of knowledge needs to be permanently encoded into model parameters.
Retrieval-Augmented Generation (RAG) connects generative models with external information sources.
A system can retrieve relevant information from documents, databases or knowledge repositories before producing an answer.
This can improve relevance and allow systems to work with proprietary or frequently changing information.
Deep Learning Applications
Deep learning has expanded into almost every major industry.
Healthcare
Applications include:
- Medical-image analysis
- Drug discovery
- Clinical documentation
- Disease-risk modeling
- Biomedical research
- Personalized medicine
Human oversight, validation and regulatory safeguards remain particularly important in healthcare applications.
Financial Services
Deep learning can support:
- Fraud detection
- Risk modeling
- Document processing
- Customer service
- Market analysis
- Cybersecurity
Manufacturing
Manufacturers use deep learning for:
- Predictive maintenance
- Quality inspection
- Robotics
- Supply-chain optimization
- Computer vision
- Process automation
Autonomous Systems
Deep learning helps autonomous systems interpret complex environments.
Applications include:
- Autonomous vehicles
- Drones
- Industrial robots
- Navigation systems
- Intelligent transportation
Cybersecurity
Deep-learning systems can analyze large volumes of activity and identify patterns associated with:
- Malware
- Network intrusion
- Fraud
- Abnormal behavior
- Security threats
However, attackers can also use AI, making cybersecurity an increasingly dynamic competition.
Education
AI can support:
- Personalized learning
- Intelligent tutoring
- Content creation
- Assessment
- Translation
- Accessibility
The role of educators remains critical for context, judgment and human development.
Science and Research
Deep learning is increasingly being applied to:
- Biology
- Genomics
- Chemistry
- Materials science
- Climate modeling
- Astronomy
- Physics
AI is therefore evolving from a tool for automating existing tasks into a technology that can assist researchers in discovering new knowledge.
Advantages of Deep Learning
Deep learning offers several important capabilities.
Automated Feature Learning
Models can learn useful representations directly from raw data.
Scalability
Performance can often improve as additional high-quality data and computational resources become available.
Complex Pattern Recognition
Deep networks can identify patterns that may be extremely difficult to specify manually.
Multimodal Capability
Modern models can increasingly integrate text, images, audio, video and other forms of information.
Reusability
Pretrained models can be adapted to numerous downstream applications.
Challenges and Limitations of Deep Learning
Despite its capabilities, deep learning has important limitations.
Computational Cost
Training advanced models can require substantial computing resources, energy and infrastructure.
Data Requirements
Many deep-learning systems depend on large quantities of suitable training data.
Explainability
Complex neural networks can be difficult to interpret.
Understanding exactly why a model produced a particular result can therefore be challenging.
Bias
Models can learn biases present in training data.
Responsible development requires deliberate evaluation, testing and mitigation.
Hallucination and Reliability
Generative models can produce plausible but incorrect information.
High-stakes applications therefore require appropriate verification and human oversight.
Privacy and Security
Training and deploying AI systems can introduce privacy, intellectual-property and cybersecurity concerns.
Environmental Impact
Large-scale training and inference require computing infrastructure and energy.
Improving AI efficiency is therefore becoming increasingly important.
Deep Learning and AI Agents
Another emerging direction is the combination of deep-learning models with systems capable of taking actions.
An AI agent can potentially:
Understand a goal → Plan → Retrieve information → Use tools → Take actions → Evaluate results → Continue
Large language and multimodal models can provide reasoning and interaction capabilities while external tools provide access to software, databases and other systems.
This is moving AI beyond simply generating answers toward executing increasingly complex workflows.
The Future of Deep Learning
Deep learning continues to evolve rapidly.
Several developments are particularly important.
1. Smaller and More Efficient Models
Progress will not depend exclusively on making models larger.
Efficiency is becoming increasingly important.
Researchers are developing techniques that reduce computational requirements while preserving useful capabilities.
2. Multimodal Intelligence
AI will increasingly integrate:
Language + Vision + Audio + Video + Sensor Data
This will make interaction with intelligent systems more natural and context-aware.
3. Specialized Foundation Models
General-purpose models will coexist with specialized models designed for areas such as:
- Medicine
- Science
- Engineering
- Finance
- Law
- Manufacturing
Domain-specific systems can combine broad AI capabilities with specialized knowledge.
4. AI at the Edge
More deep-learning processing will occur directly on:
- Smartphones
- Vehicles
- Cameras
- Robots
- Industrial equipment
- Wearable devices
Edge AI can reduce latency, improve privacy and enable systems to operate with limited connectivity.
5. More Efficient Architectures
Transformers remain enormously influential, but research continues into architectures that can process long sequences and large datasets more efficiently.
Future systems are likely to combine ideas from attention, recurrent processing, state-space models and other emerging approaches.
6. Deep Learning for Scientific Discovery
AI is increasingly becoming a research instrument.
Deep-learning systems may accelerate discoveries in:
- Medicine
- Biology
- Materials
- Climate Science
- Physics
- Chemistry
The long-term impact of AI may therefore extend far beyond automation.
7. Human-AI Collaboration
The future of deep learning is unlikely to be defined simply by machines replacing people.
A more consequential transformation may come from people working with increasingly capable intelligent systems.
AI can process information at extraordinary scale.
Humans contribute:
- Context
- Values
- Creativity
- Judgment
- Empathy
- Accountability
- Purpose
Combining these capabilities responsibly could fundamentally change how knowledge work is performed.
Deep Learning: From Pattern Recognition to Foundation Intelligence
Deep learning has undergone a remarkable transformation.
What began with simplified mathematical representations of biological neurons has evolved into systems capable of understanding language, interpreting images, generating content, assisting scientific research and interacting across multiple forms of information.
The progression can be viewed as:
Artificial Neurons → Neural Networks → Deep Neural Networks → CNNs and RNNs → Transformers → Foundation Models → Generative AI → Multimodal AI → Intelligent Agents
Yet deep learning remains an evolving technology.
Important challenges involving reliability, explainability, efficiency, privacy, security, bias and governance remain unresolved.
The next stage will therefore be determined not simply by whether AI systems become more powerful, but by how effectively those capabilities are made useful, trustworthy, accessible and aligned with human needs.
Deep learning has already transformed Artificial Intelligence.
Its next chapter may transform how humans create, communicate, discover and share knowledge.
Frequently Asked Questions
What is deep learning in simple terms?
Deep learning is a type of machine learning that uses multi-layered neural networks to learn patterns from data. Instead of humans defining every feature manually, the system learns useful representations during training.
Is deep learning the same as Artificial Intelligence?
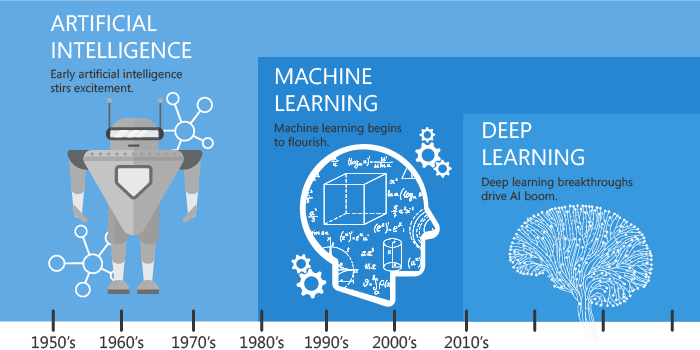
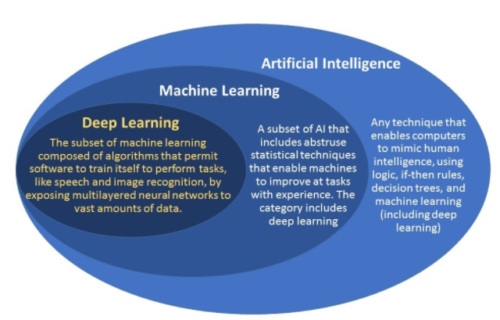
No. Artificial Intelligence is the broader field. Machine learning is a subset of AI, and deep learning is a subset of machine learning.
What is the difference between machine learning and deep learning?
Traditional machine-learning systems often rely more heavily on manually selected features and smaller models. Deep learning uses multi-layer neural networks that can automatically learn complex representations from large datasets.
Are Large Language Models based on deep learning?
Yes. Modern LLMs generally use deep neural networks based on transformer architectures.
What are transformers?
Transformers are neural-network architectures that use attention mechanisms to model relationships within data. They have become foundational to modern language models and many multimodal AI systems.
What is a foundation model?
A foundation model is a large AI model trained on broad datasets that can be adapted to many different applications rather than being limited to one narrowly defined task.
Is Generative AI part of deep learning?
Much of today’s generative AI is powered by deep-learning architectures, particularly transformers and diffusion models.
What industries use deep learning?
Deep learning is used across healthcare, finance, manufacturing, transportation, cybersecurity, education, retail, media, scientific research and many other industries.
Will deep learning replace humans?
Deep learning can automate or augment many tasks, but human judgment, accountability, domain expertise, creativity and interpersonal capabilities remain essential. In many areas, the more important development is likely to be deeper human-AI collaboration.
What is the future of deep learning?
Key directions include multimodal AI, more efficient models, specialized foundation models, edge AI, intelligent agents, scientific applications and architectures capable of processing increasingly complex information efficiently.
Conclusion
Deep learning has moved from an experimental area of Artificial Intelligence to one of the foundational technologies of the digital economy.
Its evolution has enabled machines to recognize images, understand language, generate content, analyze complex information and increasingly interact with the world through intelligent systems.
As computing, data, neural-network architectures and AI research continue to advance, deep learning will remain an important force behind the evolution of Artificial Intelligence.
The challenge ahead is not merely to build more powerful models.
It is to build AI systems that combine intelligence with reliability, innovation with responsibility, and technological capability with meaningful human value.
Comments (7 Comments)








Leave a Reply